 XML is a cheap DSL
https://unplannedobsolescence.com/blog/xml-cheap-dsl/
The lesson I took from this is that a universal data representation is worth its weight in gold. There are exactly two options in this category. In most cases you should choose JSON. If you need a DSL though, XML is by far the cheapest one, and the cost-efficiency of building on it will empower your team to spend their innovation budget elsewhere.
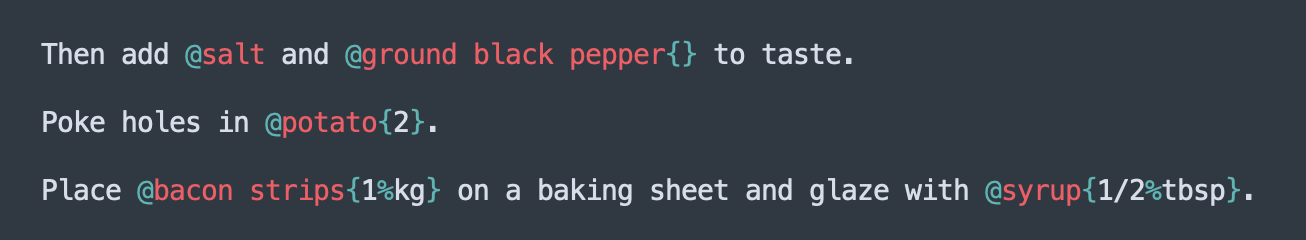
 Cooklang: recipe markup language
https://cooklang.org/
Cooklang is a simple, human-readable text format for writing recipes that can be understood by both cooks and computers.
 Virtual Scrolling for Billions of Rows — Techniques from HighTable
https://rednegra.net/blog/20260212-virtual-scroll/
TL;DR: In this post, I present five techniques related to vertical scrolling used in <HighTable>, a React component that can display billions of rows in a table while keeping good performance and accessibility.
 sohzm/jasonisnthappy: simple, embeddable document database with acid guarantees
https://github.com/sohzm/jasonisnthappy
A lightweight, embedded document database written in Rust with ACID transactions and MVCC support.
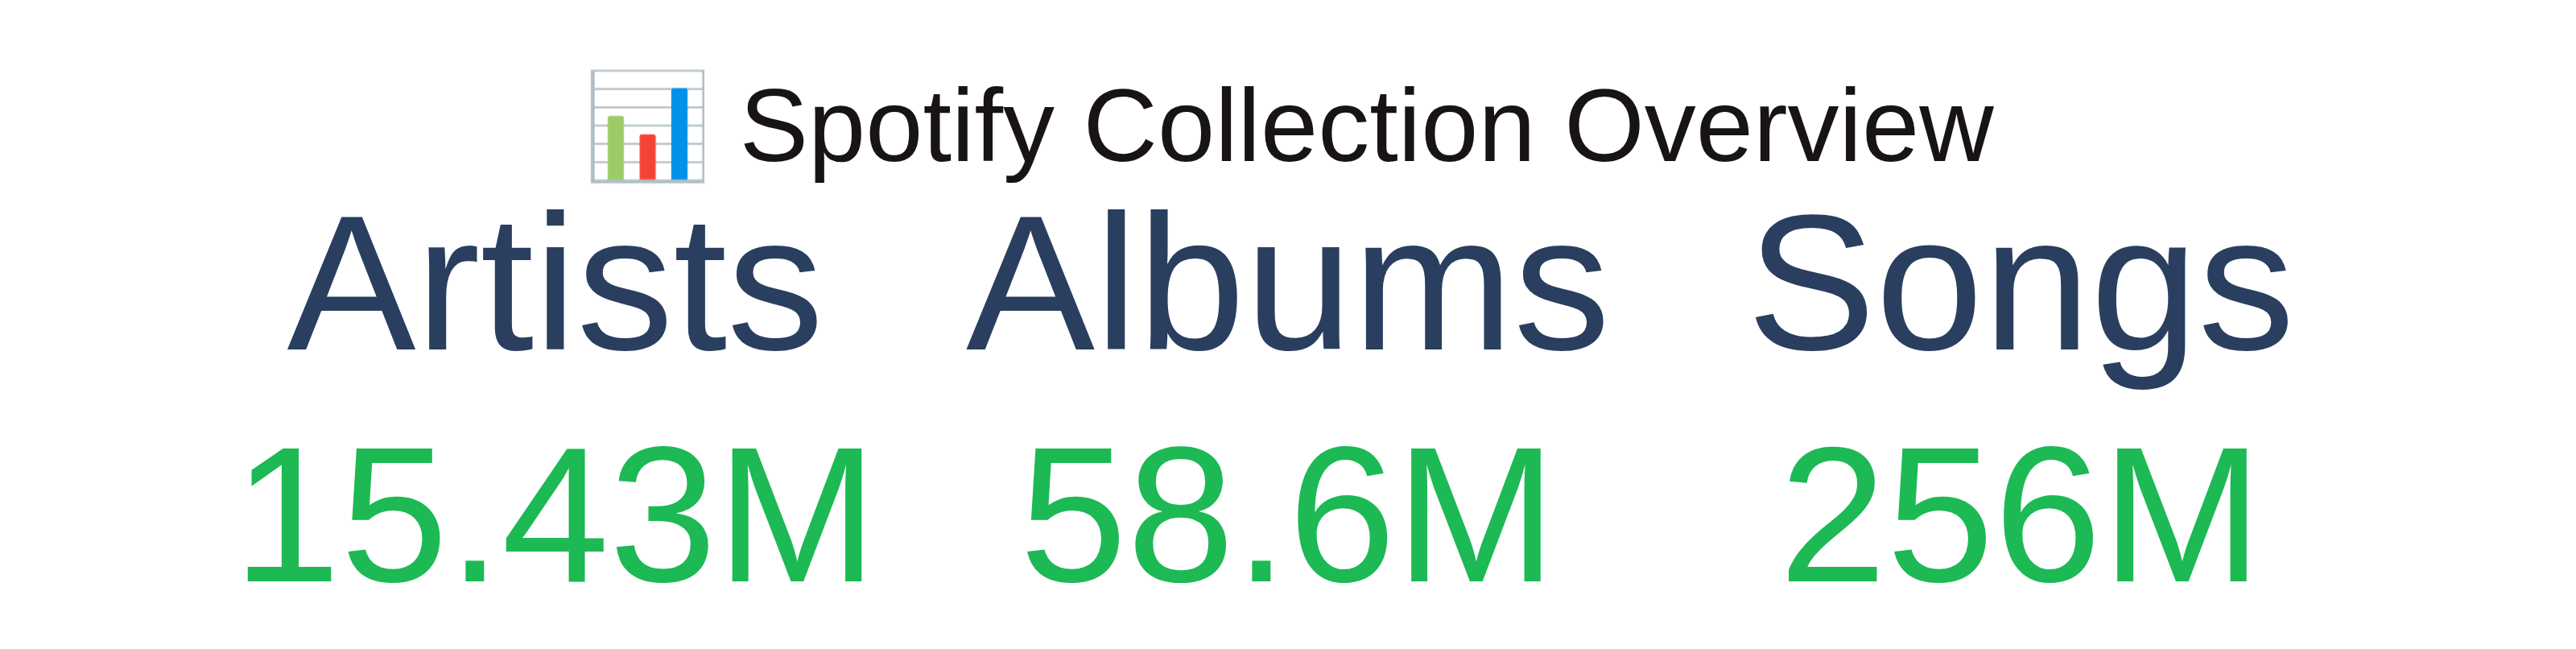
 Backing up Spotify - Anna’s Blog
https://annas-archive.li/blog/backing-up-spotify.html
We backed up Spotify (metadata and music files). It’s distributed in bulk torrents (~300TB), grouped by popularity.
This release includes the largest publicly available music metadata database with 256 million tracks and 186 million unique ISRCs.
It’s the world’s first “preservation archive” for music which is fully open (meaning it can easily be mirrored by anyone with enough disk space), with 86 million music files, representing around 99.6% of listens.
 Of the web
https://werd.io/of-the-web/
most web apps are on the web, but not of it. This seems right to me, and I suspect web instigators like Tim Berners-Lee would agree.
The odd thing is that, for a while, desktop software did exactly this. Word would save a document in a particular format, and another application written by someone else entirely could open that document. When we moved to the cloud, we signed up for a computing environment that was as much about siloing and isolation as much as it was about ease of access and maintenance.
Why Tim Berners-Lee still believes in the web | The Verge
https://www.theverge.com/podcast/814552/tim-berners-lee-world-wide-web-ai-future-interview
The right place to end up is where you’re totally in control of your data. As the power of local devices becomes greater, then the amount of stuff which gets stored locally increases… a lot of the things that people are building out there on the web are local-first, meaning that they’re designed to be able to work without the cloud. They store data either on the web, or they store the data on your local device. The good place to be is that the data is all stored on your local device. The inference is happening in your device, and you’re in control.
xvw.lol - Indexing coffee with Notion
https://xvw.lol/en/articles/notion-coffee.html
To sum up, this article will present how I set up an infrastructure to index the coffees I taste, with the goal of providing precise metrics to help characterize my preferences, using the Notion tool, while also sharing some techniques and tricks I learned during the creation of this system.
 Scripting News: Think different about developers
http://scripting.com/2025/10/23/133525.html#a133630
This is the same problem web devs have, we have to become resellers for Amazon S3. Why can't Amazon, who already has an account for every freaking person in the world, let the user own their own data, which I believe they would reallllly like. I don't want access to it, I just want to make great tools for them to use. And they're free to use other products with the data. This helps encourage data format standards. It's why the PC software market was so much more vibrant than the web developer market.
 Personal data storage is an idea whose time has come
https://blog.muni.town/personal-data-storage-idea/
Personal Data Storage has long since escaped containment as a concept pertaining to any specific protocol. Some implementations of it will be more mainstream than others, but pragmatic data coops can be protocol-agnostic and storage formats are transmutable.
As long as we have sufficient control of our own data there will always be a way to restart our social graph and digital presence elsewhere in the event of platform collapse. Let’s make the web personal again.
 File over app — Steph Ango
https://stephango.com/file-over-app
File over app is a philosophy: if you want to create digital artifacts that last, they must be files you can control, in formats that are easy to retrieve and read. Use tools that give you this freedom.
File over app is an appeal to tool makers: accept that all software is ephemeral, and give people ownership over their data.
 Synthetic Survey Data? It's Not Data
https://quantuxblog.com/synthetic-survey-data-its-not-data
My personal conclusion — as a matter of logic, empirical findings, statistical reasoning, and scientific principles — is that synthetic data has no place in survey research. I also believe the purported use cases for synthetic data are unconvincing; alternative approaches are superior in their results and are less risky in practice. And there are important questions about research ethics that each of us should consider.
 How I Track My Blog’s Analytics with Val Town
https://orjpap.github.io/valtown/http/analytics/blog/jekyll/2025/04/15/blog-analytics.html
Random morning thoughts: how many people actually visit this blog? Where do they come from? What if I could just spend a little time to build my own analytics?
xan/docs/LOVE_LETTER.md at master · medialab/xan
https://github.com/medialab/xan/blob/master/docs/LOVE_LETTER.md
It is therefore my intention, through this article, to write a love letter to this data format, often criticized for the wrong reasons, even more so when it is somehow deemed "cool" to hate on it. My point is not, far from it, to say that CSV is a silver bullet but rather to shine a light on some of the format's sometimes overlooked strengths.
 Maintaining control of our data with personal databases | N=1 (marcua’s blog)
https://blog.marcua.net/2025/01/05/maintaining-control-of-our-data-with-personal-databases
The fundamental problem is that in using most modern consumer-oriented applications, we lose control of the data we share with those applications. In creating documents, writing emails, or tracking our exercise or other activities, we share data with an application that’s useful for a particular purpose, but also allow the data live in a database controlled by the application’s owner. With the data outside of our control, it can then be restricted, lost, leaked, sold, resold, and exploited. The groups that control these databases accrue most of the benefits, and we accrue most of the costs.
 Halloween 2024. Cruft Manor has Halloween traditions… | by Michael Pusateri | Oct, 2024 | Medium
https://cruftbox.medium.com/halloween-2024-fba108e7e7a9
Cruft Manor has Halloween traditions every year:
1. We give out full size candies
2. Make a listing of all costumes
3. Make a timelapse movie
 JSON-LD is good, actually.
https://nikolas.ws/what-is-jsonld-for
In which we try and understand what JSON-LD is all about, what it's good for, and why it's interesting and cool.
 Dogsheep | dogsheep.github.io
https://dogsheep.github.io/
Dogsheep is a collection of tools for personal analytics using SQLite and Datasette.
Dogsheep | dogsheep.github.io
https://dogsheep.github.io
Dogsheep is a collection of tools for personal analytics using SQLite and Datasette.
 Tangle: a JavaScript library for reactive documents
http://worrydream.com/Tangle/
Tangle is a JavaScript library for creating reactive documents. Your readers can interactively explore possibilities, play with parameters, and see the document update immediately. Tangle is super-simple and easy to learn.
Tangle: a JavaScript library for reactive documents
http://worrydream.com/Tangle
Tangle is a JavaScript library for creating reactive documents. Your readers can interactively explore possibilities, play with parameters, and see the document update immediately. Tangle is super-simple and easy to learn.
 Doing the SDE Conversions - Fuzzwork Enterprises
https://www.fuzzwork.co.uk/2013/09/05/sde-conversions/
I’m not planning on stopping doing these any time soon, as I need them for my own porpoises, but I thought it might be worth having a few instructions out there, so people can run their own conversions of the EVE SDE. Just in case I get hit by a bus, or mauled by crazed Cetaceans.
Doing the SDE Conversions - Fuzzwork Enterprises
https://www.fuzzwork.co.uk/2013/09/05/sde-conversions
I’m not planning on stopping doing these any time soon, as I need them for my own porpoises, but I thought it might be worth having a few instructions out there, so people can run their own conversions of the EVE SDE. Just in case I get hit by a bus, or mauled by crazed Cetaceans.
EVE Online data dumps
https://www.fuzzwork.co.uk/dump/
Everything here belongs to CCP. I'm just making conversions available
EVE Online data dumps
https://www.fuzzwork.co.uk/dump
Everything here belongs to CCP. I'm just making conversions available
 Low Friction Personal Data Collection - Aaron Parecki
http://aaronparecki.com/presentations/2013/06/19/1/low-friction-personal-data-collection
Have you ever wanted to track your movements, sleep, what you eat, who you spend time with, and all sorts of other personal data? In this talk I'll describe the tools I've been able to successfully use to track aspects of my life.
 SQLite: the Case against Custom Application File Formats | Stackful.io
http://stackful.io/blog/sqlite-the-case-against-custom-application-file-formats/
So, here is my thought experiment -- whenever you have the urge of building a custom file format, just don't.
SQLite: the Case against Custom Application File Formats | Stackful.io
http://stackful.io/blog/sqlite-the-case-against-custom-application-file-formats
So, here is my thought experiment -- whenever you have the urge of building a custom file format, just don't.
 Proposed standards for the care and feeding of user generated content – Jeffrey Zeldman Presents The Daily Report
http://www.zeldman.com/2012/07/25/proposed-standards-for-the-care-and-feeding-of-user-generated-content/
Treat our data like it matters. Keep it secure and protect our privacy, of course—but also maintain serious backups and respect our choice to delete any information we’ve contributed.
No upload without download. Build in export capabilities from day one.
If you close a system, support data rescue. Provide one financial quarter’s notice between announcing the shutdown and destroying any user-contributed content, public or private, and offer data export during this period. And beyond that three months? Make user-contributed content available for media-cost purchase for one year after shutdown.
Proposed standards for the care and feeding of user generated content – Jeffrey Zeldman Presents The Daily Report
http://www.zeldman.com/2012/07/25/proposed-standards-for-the-care-and-feeding-of-user-generated-content
Treat our data like it matters. Keep it secure and protect our privacy, of course—but also maintain serious backups and respect our choice to delete any information we’ve contributed.
No upload without download. Build in export capabilities from day one.
If you close a system, support data rescue. Provide one financial quarter’s notice between announcing the shutdown and destroying any user-contributed content, public or private, and offer data export during this period. And beyond that three months? Make user-contributed content available for media-cost purchase for one year after shutdown.
 Tabletop
http://builtbybalance.com/Tabletop/
Tabletop takes a Google Spreadsheet and makes it easily accessible through JavaScript. With zero dependencies!
Tabletop
http://builtbybalance.com/Tabletop
Tabletop takes a Google Spreadsheet and makes it easily accessible through JavaScript. With zero dependencies!
 javascript - How to upload a screenshot using html2canvas? - Stack Overflow
http://stackoverflow.com/questions/9250505/how-to-upload-a-screenshot-using-html2canvas
Using html2canvas how can I save a screen shot to an object? I've been exploring the demos, and see that the function to generate the screenshot is generated as follows:
 SUMO and migrating large amounts of data
http://embrangler.com/2010/12/migrating-large-amounts-of-data/
Data migration is a complicated problem. It’s one of those things nobody wants to do, because it’s mostly tedious, not engaging, and also important to get right. Often times you have to compromise. I’ll talk a bit about the history of SUMO’s data, decisions the product and development team have made regarding its migration, and things I’ve learned from the experience.
SUMO and migrating large amounts of data
http://embrangler.com/2010/12/migrating-large-amounts-of-data
Data migration is a complicated problem. It’s one of those things nobody wants to do, because it’s mostly tedious, not engaging, and also important to get right. Often times you have to compromise. I’ll talk a bit about the history of SUMO’s data, decisions the product and development team have made regarding its migration, and things I’ve learned from the experience.
 Leftronic goes true Real-Time with Node.js and Redis Pub/Sub! - Leftronic Blog
http://blog.leftronic.com/leftronic-goes-true-real-time-with-nodejs-and
We have several Django servers behind an EC2 load balancer, as well as a few Celery boxes, a RabbitMQ box, a Node.js box, and a Redis box.
 CouchDB "Joins" - Christopher Lenz
http://www.cmlenz.net/archives/2007/10/couchdb-joins
Obvious to Damien, but not at all obvious to the rest of us: it's fairly simple to make a view that includes both the content of the blog post document, and the content of all the comments associated with that post. The way you do that is by using complex keys. Until now we've been using simple string values for the view keys, but in fact they can be arbitrary JSON values, so let's make some use of that:
 Steven Poole: Whatever made you think it was your data anyway?
http://stevenpoole.net/blog/whatever-made-you-think-it-was-your-data-anyway
In case it helps, I hereby declare the following iron law of “free” internet services:
If you’re not paying for something, you have no reason to expect it to be there tomorrow.
This is an important corollary to the law “If you’re not paying for something, you’re not a customer; you’re the product being sold”.
 Don't use MongoDB | Hacker News
http://news.ycombinator.com/item?id=3202081
From CTO of 10gen
First, I tried to find any client of ours with a track record like this and have been unsuccessful. I personally have looked at every single customer case that’s every come in (there are about 1600 of them) and cannot match this story to any of them. I am confused as to the origin here, so answers cannot be complete in some cases.
 Detecting Support for data: URIs | Weston Ruter
http://weston.ruter.net/2009/05/07/detecting-support-for-data-uris
The data: URI scheme is now supported by the most current version of every major browser, including Internet Explorer. Because of this I wanted to use CSS background images encoded with data: URIs in a current project at Shepherd Interactive. Why? The first rule of High Performance Websites is to Minimize HTTP Requests. By storing background images directly in the stylesheet only one HTTP request is then necessary to fetch the stylesheet and the images all at once. Furthermore, by giving that stylesheet a far-future cache expiration date the browser will never need to request it again.
 Persistent Trees in git, Clojure and CouchDB « EclipseSource Blog
http://eclipsesource.com/blogs/2009/12/13/persistent-trees-in-git-clojure-and-couchdb-data-structure-convergence
"This is a tale of three images. I found these images while investigating the internals of several different applications. There are some really neat software projects emerging at the moment, and as a developer I always find it interesting to take a look at the implementation details, because there is often a lot to be learned. It’s not always something you might need right now, but maybe a few years down the line you may be confronted with a similar problem. Plus – in my opinion – knowing a bit about the internals of a program helps reasoning about its behaviour."
 Grafitter // Visualizing Your Life on Twitter, IM, Delicious, and Blogger.
http://www.grafitter.com
"Grafitter is a personal informatics tool for collecting and exploring information about your habits and patterns."
 NoSQL vs. RDBMS: Let the flames begin! – stu.mp
http://stu.mp/2010/03/nosql-vs-rdbms-let-the-flames-begin.html
"I guess what I’m saying is that my decision to use NoSQL, and I’m guessing others’ decisions to do so, has less to do with the fact that we can’t squeeze a few thousand writes a second out of MySQL and more to do with management and cost overhead. NoSQL solutions allow us to serve absurd amounts of data for a really, really low price. I’m happy to put my $/write, $/read, and $/GB numbers for my NoSQL setup against anyone’s RDBMS numbers.
We’re not nearly as dumb as everyone thinks we are; I promise."
 Edward Vielmetti - Downtown parking information by telephone project: my part is over
http://vielmetti.typepad.com/vacuum/2009/05/downtown-parking-project-over.html
"Sorry I ever brought it up, sorry for any hurt feelings. It was wrong of me to think that I could make any progress without the support of the organization providing the data, and wrong of me to press on regardless of the cost. Someone else will have to care - I give up. It's just not worth it and it's bad for my health to care and to spend too much time around parking structure fumes."
Edward Vielmetti - I am not an "information activist" or a "civic minded data freak", thank you very much
http://vielmetti.typepad.com/vacuum/2009/05/i-am-not-an-information-activist-or-a-civic-minded-data-freak-thank-you-very-much.html
"So if I ask for that page of numbers as the spreadsheet it was originally, and a public records officer for a public body gives it to me as a bitmap, I'm going to ask again and keep asking publicly and perhaps uncomfortably until we both understand that this is a routine request and that compliance with routine requests is much easier than making everything an exception - because maybe, just maybe, I can replace that FOIA letter with a tiny shell script and we can just go about our business."
 Design Proposals
http://risherry.blogspot.com/2009/02/mozilla-lizardfeeder-proposal-goal-of.html
 Monkeying with the Lizard Feeder
http://surfmind.com/muzings?cpage=1&p=237#comment-312760
"The call to action is to build on the Lizard Feeder concept with anything from ideas to pixels to code. I hacked up a grease monkey script that weights the data-source checkbox & label on the left according to the volume of flow. This provides a bit of focus + context for the recent stream. The implementation is a minimal, bit-of-an-evening starter kit (MPL) for more interesting creations."
 Visualizing Mozilla Community :: The Mozilla Blog
http://blog.mozilla.com/blog/2009/01/26/visualizing-mozilla-community
 Visualizing Mozilla | intothefuzz.com
http://www.intothefuzz.com/2009/01/26/visualizing-mozilla
 getluky.net » A Warning About the Real Cost of Microformats
http://getluky.net/2009/01/08/a-warning-about-the-real-cost-of-microformats
"Anyway, here’s the question I want to put into the reader’s mind: should one spend time and effort making a frontend into an informal API through microformats, or to instead spend it on building a fully supported API or data publishing system that exists and operates separately? I think my stance is clear - i’m not against the theory of microformats, but i’m certainly going to differ with anyone who thinks it’s practical."
Vacuum - Edward Vielmetti in Ann Arbor, Michigan 48104: web two point naught: watching the shutdown of free web 2.0 services
http://vielmetti.typepad.com/vacuum/2008/12/web-two-point-naught-watching-the-shutdown-of-free-web-20-services.html
"Web 2.0 is over. Back up your important data now, or decide which parts of it you are willing to discard."
 but she's a girl... » Using Tinderbox as a task timer
http://www.rousette.org.uk/blog/archives/using-tinderbox-as-a-task-timer
This is just about time tracking, but with personal data tracking looking like the next big thing I wonder how well Tinderbox could be pressed into used in recording and studying personal data points in general?
 Terrell Russell: This Old Network : WordCamp SF 2008 - DiSo and more
http://weblog.terrellrussell.com/2008/08/wordcamp-sf-2008-diso-and-more
"There is a growing awareness of the need for self-hosted data - the individual should own and control their own stuff."
 Graphite: Graphite - Enterprise Scalable Realtime Graphing
http://graphite.wikidot.com
"Graphite is a highly scalable real-time graphing system. As a user, you write an application that collects numeric time-series data that you are interested in graphing, and send it to Graphite's processing backend, carbon, which stores the data in Graphi
 Study: .gov web sites should focus on RSS, XML—not redesigns
http://arstechnica.com/news.ars/post/20080603-study-gov-websites-should-focus-on-rss-xmlnot-redesigns.html
"David Robinson, Harlan Yu, William Zeller, and Ed Felten, all of Princeton's Information Technology Policy Center, suggest that government officials abandon the dream of developing usable web sites, and instead focus on providing raw public data such as

 Enron Email Dataset
http://www.cs.cmu.edu/~enron
"It contains data from about 150 users, mostly senior management of Enron, organized into folders. The corpus contains a total of about 0.5M messages."
 the ryan king » Introducing Conveyor
http://theryanking.com/entries/2008/02/26/introducing-conveyor
"The future for large websites’ data storage is likely a collection of special purpose data stores: GFS/MapReduce for batch jobs, inverted indexes for search and fast retrieval of small result sets and relational databases for smaller datasets which nee
 Overcoming data friction « Jon Udell
http://blog.jonudell.net/2008/02/20/overcoming-data-friction
"For me, web screen-scraping provides the kind of challenge that other people get from, say, solving crossword puzzles. But it’s not the highest and best use of anyone’s time."
 poshformats - Microformats
http://microformats.org/wiki/poshformats
 Data’s Head For Sale - Slice of SciFi
http://www.sliceofscifi.com/2008/01/08/datas-head-for-sale
"A “Star Trek: The Next Generation” era prop of Data’s head from the episode ‘Time’s Arrow’ is up for auction. This unique piece of Star Trek history is a collector’s dream."
 Posterity | Jeni's Musings
http://www.jenitennison.com/blog/node/59
"here I am using radically different software, in a completely different world, and these pieces from my past are lost, irretrievable because of the formats used to save them (as well as the hardware on which they’re saved: it’s getting harder to read
 Wired News: The Dead Formats Society
http://www.wired.com/news/columns/0,70946-0.html?tw=rss.index
"My CD-ROM is accessible only to cranks and connoisseurs, members of the "dead formats society" who've invested in the dead tech required to play it."
 Google Data APIs Protocol | 2006-04-20 | BitWorking
http://bitworking.org/news/Google_Data_APIs_Protocol
"Google has released their very akwardly named Google Data APIs Protocol, which we'll just abbreviate to GData."
 Google Data APIs Overview
http://code.google.com/apis/gdata/overview.html
"The Google data APIs ("GData" for short) provide a simple standard protocol for reading and writing data on the web."
Google Calendar Data API
http://code.google.com/apis/gdata/calendar.html
"Google Calendar allows client applications to view and update calendar events in the form of Google data API ("GData") feeds."
Google Data APIs Protocol
http://code.google.com/apis/gdata/protocol.html
"This document describes the protocol used by the Google data APIs ("GData"), including information about what a query looks like, what results look like, and so on."
 ongoing · Don’t Invent XML Languages
http://www.tbray.org/ongoing/When/200x/2006/01/08/No-New-XML-Languages
"Here’s a radical idea: don’t even think of making your own language until you’re sure that you can’t do the job using one of the Big Five: XHTML, DocBook, ODF, UBL, and Atom."
 EA IFF 85
http://www.szonye.com/bradd/iff.html
"Customers should be able to move their own data between independently developed software products. "
 Wikidata - Meta
http://meta.wikimedia.org/wiki/Wikidata
"Wikidata is a proposed wiki-like database for various types of content."
 The Elements of Meaningful XHTML
http://tantek.com/presentations/2005/09/elements-of-xhtml
Deeper into semantic XHTML
 spinneret.org - The Spinneret Project
http://www.spinneret.org
"Spinneret is a semi-structured storage engine that can be thought of as an extended tuple storage system. It takes the best aspects of relational, object, and hierarchical databases and throws away the dead weight associated with those technologies."
Spinneret Query Language Primer
http://www.spinneret.org/doc/query-language.html
"This document briefly introduces SPQL (Spinneret Query Language). It will be updated as the language definition continues to be refined."
 The Real World as One Giant Database
http://www.citris-uc.org/newsletter/2003_Newsletters/december_2003/feature.htm